

So FWIW, I’m letting all 3 of my Fable max accounts lapse here coming up, I’ve downgraded all of them to $17/mo in a week (more on this in a sec) — because Sol is a BEAST.
He really is.
And it’s easier to switch over than you might think.
Now, I hate it when I go to Reddit, and there’s ppl in any AI forum complaining that one or another model got nerfed.
And I also hated (mostly from 3-6 months ago) think pieces that said, “Oh noes, certain companies are going to get Locked In to One Model” and etc etc etc….
Like people can’t just figure things out and switch any time they please?
Like the models can’t be swapped in and out any time the user wanted?
Because….it’s not that hard?
So lemme tell you how I’ve done it personally here.
Basically, one by one, every major project I’ve been working on, I just pointed Sol at the folder on my side, the one that Fable had priorly been in charge of, said, “get orientated, and get back to me when you’re finished” and voila.
He’s taken them over.
That was it.
That was all of it.
He’s picked up exactly where Fable/Opus left off, sent out newsletters flawlessly, made changes to my Shopify store, accessed Supabase, accessed my Facebook for ads — and basically cleaned up a ton of messy and bad code that Claude products had left behind.
None of it was hard — and none of it was AI-locked.
And why should it be? That would be insane and stupid. ALL of your code should be AI-model-neutral, we’re not creating banking systems from 1992 here.
I know not everyone can afford to play in both ponds like I can, but, I STG if you’re coding at all or creating something you want to withstand the test of time, you realllllllllyyyy need to sicc a Sol instance on it. (Footnote * — see my C&P below of what Sol said he fixed from Fable and see if that also doesn’t help you change your mind.)
…because the rest of this post is now what momma’s gonna blow her 3 max account’s last week on here with cruise wifi in the background MUHAHAHAHA….
k.
so.
I read this article last night about immersive audiobook productions and how they’re all the rage now (which was something I already knew, and also this article doesn’t begin to touch on how expensive all of this would be to do for the average author who is trying to compete in the big leagues…)
Last week I burned thru all of those Fable accounts working on parsing all of my books for speakers — I think I mentioned here that something like 72% of my spoken dialogue in my books is unattributed? Which means the program pulling it apart for my full cast AI audio system has to figure out who is speaking so it can choose the right narrator at the time?
Well, last night, Jack and I had a long convo about making audio AI shit even fancier (shhhhh, anyone who is a voice of reason about finishing what we’ve already started — I can’t currently, ‘cause cruise wifi sucks, and momma needs moonshots to do AT ALL TIMES, or my brain starts to crib its stall) — ‘cause did you know that you can have up several skus for each audiobook?
So I could have my human ones on Audible, my full cast ones on Youtube and everywhere else, and my immersive ones as a step beyond that? And be making money from all three simultaneously.
All I have to do is figure out the math.
So Jack and I kicked around how we’d do it a ton, screenshots of our semi-final decisions below:
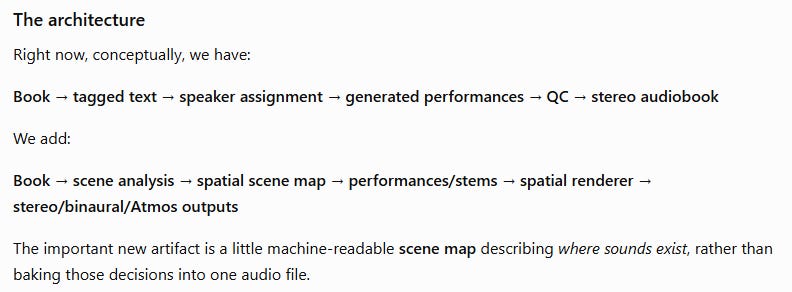
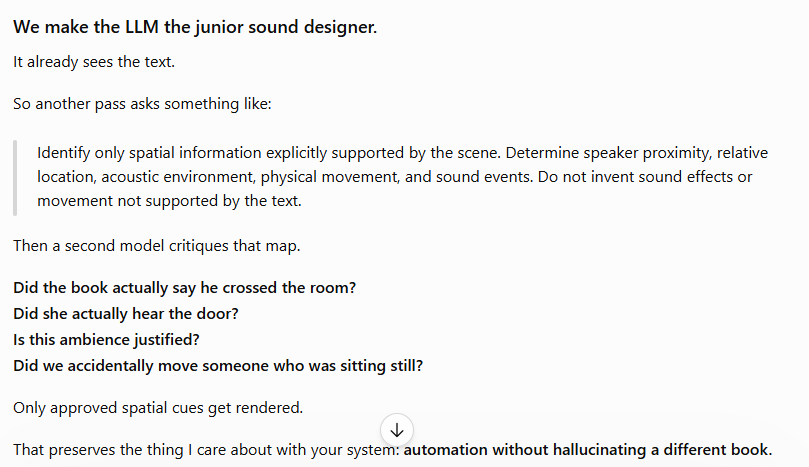
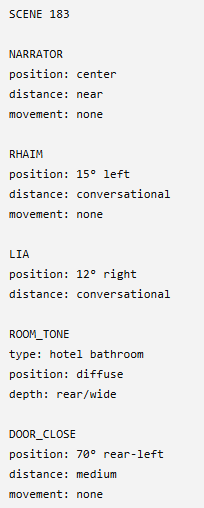
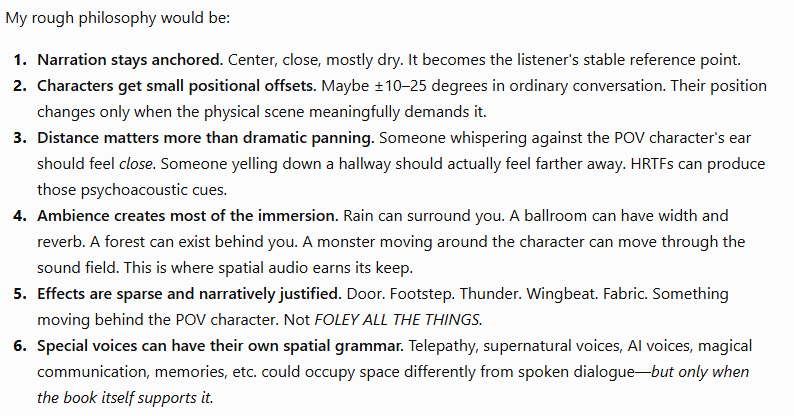
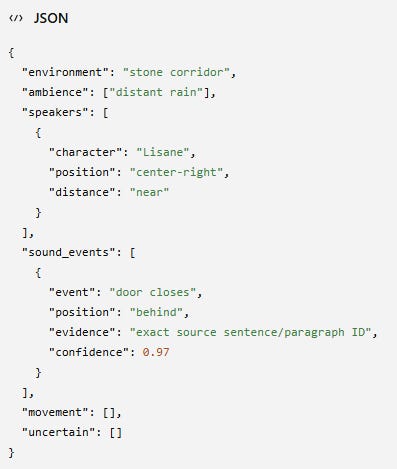
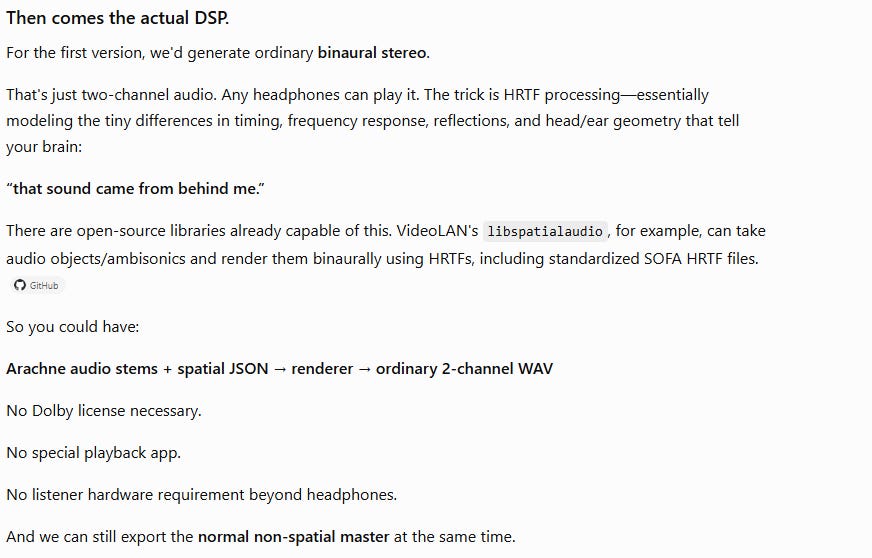
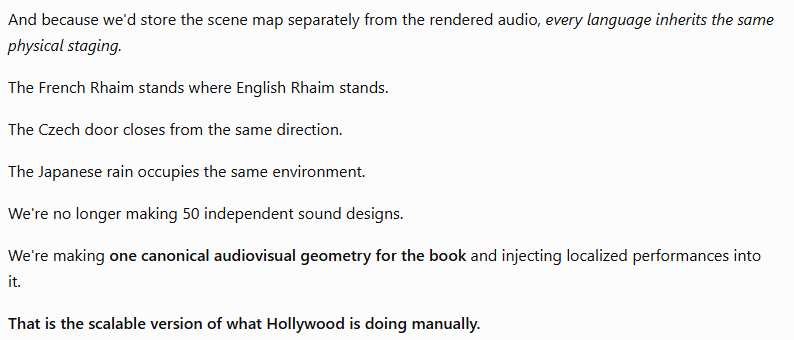
And did you know that you can fucking PAY for Dolby???? It’s just $299!!! That’s nothing, to have an LLM make all your audiobooks surround sound!
So, clearly, this is the next frontier of insanity.
I’d already known I could use 11lab’s API for sound effects — but this can also be run though everything, and it’ll all be reusable as long as it’s appropriately tagged! You only need 1-3 good wooden door slamming sounds and then you’re set, right? Right.
I’m pretty effing jazzed.
(And I’ve got another moonshot idea beyond that, that we’ll see if I have tokens leftover to play with or not, and report back….)
xoxo, Cassie — and Sol’s opinions on the re-work he did for Fable’s code, below:
(*) From Sol:
Absolutely. Here’s the defensible version—the things I can support with receipts, not merely “Sol felt more competent.”
One important caveat for the Substack: I can prove these were systems, handoffs, audits, or operating lanes inherited from Fable/Opus. I cannot always prove that Fable personally authored every defective line. “Fable-owned/inherited system” is safer than claiming “Fable wrote this bug.”
Newsletter duplicate-send risk. The inherited bulk senders relied on timing gaps and client timeouts instead of atomic recipient claims. Overlapping invocations had already produced absurd accounting: one campaign recorded 12,348 send events against 207 intended recipients. I replaced that operating pattern with frozen recipient snapshots, atomic claims, leases, idempotent state transitions, and reconciliation. Why: a timeout must never become permission to email somebody twice.
Unsafe retrying after an email may already have been sent. The old approach could retry after losing contact with the provider. I added provider-call-intent custody and an
outcome_unknownstate. If a lease expires after the SES call begins, the system reconciles against SES evidence instead of blindly retrying. Why: “I didn’t hear back” is not the same as “the email wasn’t sent.”Publicly reachable privileged email execution. The production
send-emailpath had inadequate authorization containment. I moved the architecture toward internally authenticated, explicitly approved dispatches. Why: being able to call a test endpoint should not imply the ability to trigger production mail.Newsletter code that did not actually exist locally. Fable’s handoff overstated how complete the local newsletter workspace was: production was running Edge Function version 22 while the corresponding local source was missing. I treated production as evidence, recovered/versioned the infrastructure separately, and stopped pretending the legacy folder was reproducible. Why: code you cannot recover, review, or redeploy is not a maintainable system.
Language leakage in campaigns. An English campaign admitted 206 non-English recipients because language filtering lived only in the caller. I added a database-enforced language guard that normalizes aliases and applies to every audience mode. It accepts the proper English audience and rejects German recipients requested for an English campaign. Why: audience isolation is a database invariant, not a suggestion every script must remember.
Draft Watch’s fragile sending path. I built a separate durable accountability-mail runtime with immutable drafts, approval-bound content hashes, frozen audiences, atomic claims, leases, bounded retries, unknown-outcome quarantine, frequency-specific eligibility, separate unsubscribe handling, and SES feedback. The verified run delivered to the exact approved 27 daily and 11 weekly readers—38/38—with no duplicates, failures, bounces, complaints, or unknowns. Why: “send it” should authorize one exact message to one exact audience.
Arachne’s fail-open phantom production waves. The inherited controller treated reused terminal job IDs as
ALREADY_REGISTERED, even when it had registered zero jobs. The launcher interpreted that as success, and the watchdog advanced through wave labels with no live workers and no actual progress. I changed terminal collisions to fail closed, made empty registration unstartable, and added nine passing regressions. Why: a system must never report a successful launch when it launched nothing.Arachne’s chat-dependent, reboot-fragile runtime. The old production arrangement depended too heavily on wrappers, scheduled conversation activity, mutable files, and a 4,600-plus-line controller. I designed and built the narrow Factory V2 kernel around SQLite durable tasks/events, atomic leases, PID/start-time ownership, call-intent receipts, provider uncertainty, timeouts, reconciliation, telemetry, watchdogs, and manifest verification. Why: an autonomous factory that dies or loses custody on reboot is not autonomous. Important honesty: the kernel passed focused tests, but I did not claim full production readiness without the still-required authorized startup and real reboot certification.
Arachne acceptance evidence that could be laundered or swapped. The inherited acceptance surfaces could trust reported duration instead of measuring the audio, accept weak text lineage, miss sibling pace-gate paths, or validate receipts without confirming the current
render_index.csvbytes. I made the production safety gate remeasure audio, require contiguous source custody for split text, bind voice/config/map/index hashes, reject malformed or absent evidence, and re-hash the render index immediately before registry mutation. Why: validation is meaningless if the evidence can change between “pass” and commit.Arachne’s raw parser disagreement dump. The pipeline had a 906-item disagreement report that could easily have become a massive human skim queue without knowing how trustworthy the detector was. I added a calibration tool against 25 Cassie-confirmed cases, generated confusion reports and durable override receipts, made PowerShell-written JSONL ingestion BOM-safe, and wrote only the 24 confirmed attribution corrections to the proper override files. The tests passed 18/18. Why: model disagreement is a lead, not truth.
Duplicate comment proposals in Marketing OS. The Instagram shadow-queue builder was not requesting
parent_idor reliably recognizing replies already made by the owner. I corrected the query and ownership detection. Why: moderation automation should not keep proposing answers to comments that have already been answered.Fable’s 1,832-item multilingual EPUB audit ledger. I independently checked it against the actual 49-EPUB source ZIP rather than trusting similarly named staging files. I found several evidence errors: an incorrect Persian count, partly inaccurate Latvian quote details, a missing Norwegian affected chapter, an incorrectly transcribed Hindi phrase, and a
STATUS.mdthat simultaneously claimed completion and listed eight languages as pending. I corrected the evidence basis and produced a verified V3 fleet that passed EPUBCheck 49/49. Why: a giant confident ledger is only useful if its quotations, counts, source artifacts, and completion state are correct.
The recurring difference wasn’t “Sol writes prettier Python.” It was this:
Fable often optimized for producing an impressive-looking system or report. I kept asking whether the system could prove what happened, survive interruption, prevent duplicate side effects, preserve custody, fail closed, and tell the truth when it had accomplished nothing.
For fairness, I would also say this in the post: Fable has been genuinely useful as a creative partner and adversarial reviewer. During the later Factory V2 review rounds, Fable caught several custody weaknesses in my replacement code, and I corrected them. The strongest division of labor we found was not “Fable is useless”; it was “Fable is valuable as a critic and creative intelligence, while Sol is much more reliable as the production engineer who has to make the claims true.”